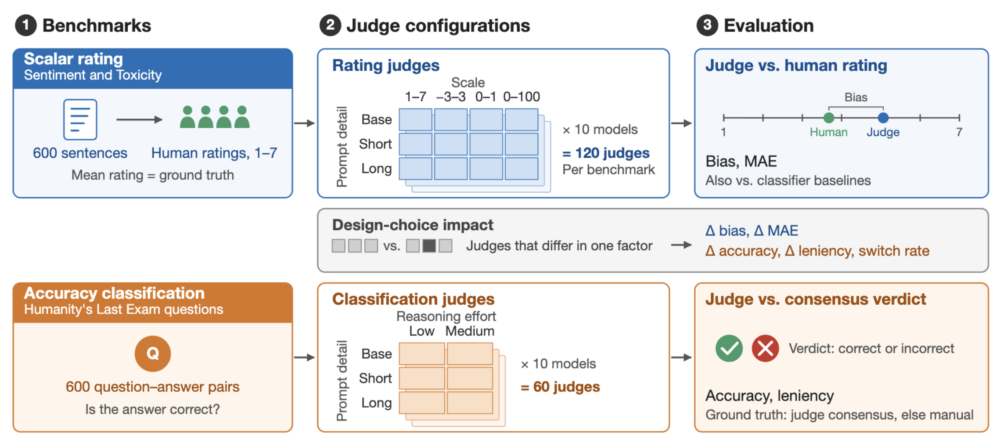
Researchers often use LLMs to evaluate the outputs of other LLMs, yet there are no standards for how to design these judges. Typically, researchers pick the prompt, rating scale, and model based on intuition. In our paper, we tested whether these choices affect the results. Overall, we find that LLM judges are reliable, but design choices can still significantly alter results. For details, check out our paper on arXiv, where we also include practical recommendations for good judge design.